Our mission is to help computational modelers develop, document, and share their computational models in accordance with community standards and good open science and software engineering practices. Model authors can publish their model source code in the Computational Model Library with narrative documentation as well as metadata that supports open science and emerging norms that facilitate software citation, computational reproducibility / frictionless reuse, and interoperability. Model authors can also request private peer review of their computational models. Models that pass peer review receive a DOI once published.
All users of models published in the library must cite model authors when they use and benefit from their code.
Please check out our model publishing tutorial and feel free to contact us if you have any questions or concerns about publishing your model(s) in the Computational Model Library.
Displaying 10 of 203 results for "Nuno Pinto" clear search
A Benchmark Test for LLM Persona Agents in a Macroeconomic Simulation
Taewan You | Published Thursday, October 08, 2026This model couples a two-asset heterogeneous-agent New Keynesian macroeconomy with a household layer that can be driven in two ways. One is a conventional calibration. The other is a set of large-language-model persona agents built from real survey households in Korea (NaSTaB), the United States (PSID) and Italy (SHIW). Each persona is given its balance sheet, income and prices, and reports consumption, saving and labour supply. A feasibility layer enforces the budget constraint. A conditional-mean surrogate then turns these decisions into a propensity surface. That surface reaches the macroeconomic block through a single channel, the intertemporal marginal propensity to consume matrix. Because of this, a calibrated “twin” can be aligned with the generative layer exactly, and the two can be compared policy by policy.
Both layers are then scored against the held-out consumption of the same households. The model’s role is to serve as a benchmark: it tests whether generative agents add information beyond the balance sheet, and whether that information matches real behaviour.
The deposit contains:
…
Composite Collective Decision Making - ant colony foraging model
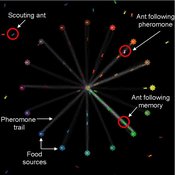
Tomer Czaczkes Benjamin I Czaczkes | Published Thursday, December 17, 2015The model explores how two types of information - social (in the form of pheromone trails) and private (in the form of route memories) affect ant colony level foraging in a variable enviroment.
Peer reviewed FishCensus
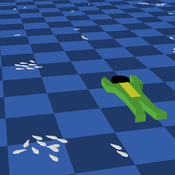
Miguel Pais | Published Tuesday, December 06, 2016 | Last modified Thursday, February 09, 2017The FishCensus model simulates underwater visual census methods, where a diver estimates the abundance of fish. A separate model is used to shape species behaviours and save them to a file that can be shared and used by the counting model.
Informal risk-sharing cooperatives : ORP and Learning
Juliette Rouchier Victorien Barbet Renaud Bourlès | Published Monday, February 13, 2017 | Last modified Tuesday, May 16, 2023The model studies the dynamics of risk-sharing cooperatives among heterogeneous farmers. Based on their knowledge on their risk exposure and the performance of the cooperative farmers choose whether or not to remain in the risk-sharing agreement.
Agent-based model of WiFi tracking system in urban environment
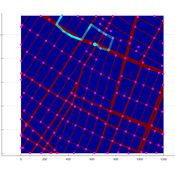
Christopher Thron Khoi Tran | Published Friday, April 21, 2017This code simulates the WiFi user tracking system described in: Thron et al., “Design and Simulation of Sensor Networks for Tracking Wifi Users in Outdoor Urban Environments”. Testbenches used to create the figures in the paper are included.
Peer reviewed COMOKIT
Patrick Taillandier Alexis Drogoul Benoit Gaudou Kevin Chapuis Nghi Huyng Quang Doanh Nguyen Ngoc Arthur Brugière Pierre Larmande Marc Choisy Damien Philippon | Published Tuesday, May 26, 2020 | Last modified Wednesday, July 01, 2020In the face of the COVID-19 pandemic, public health authorities around the world have experimented, in a short period of time, with various combinations of interventions at different scales. However, as the pandemic continues to progress, there is a growing need for tools and methodologies to quickly analyze the impact of these interventions and answer concrete questions regarding their effectiveness, range and temporality.
COMOKIT, the COVID-19 modeling kit, is such a tool. It is a computer model that allows intervention strategies to be explored in silico before their possible implementation phase. It can take into account important dimensions of policy actions, such as the heterogeneity of individual responses or the spatial aspect of containment strategies.
In COMOKIT, built using the agent-based modeling and simulation platform GAMA, the profiles, activities and interactions of people, person-to-person and environmental transmissions, individual clinical statuses, public health policies and interventions are explicitly represented and they all serve as a basis for describing the dynamics of the epidemic in a detailed and realistic representation of space.
…
HousingABM_Japan: An Agent-Based Model of Price and Rent Amplification in the Tokyo Housing Market
Eiki Tamama | Published Sunday, September 06, 2026HousingABM_Japan is a NetLogo agent-based model of the residential market of Tokyo’s 23 wards. It evaluates whether a single parameter configuration can jointly reproduce key features of prices, rents, yields, and market turnover across distinct market regimes from 2001 to 2025, with particular attention to demand- and supply-side trend-following during the 2021–2025 price surge.
The model builds on the Bank of England housing-market lineage (Baptista et al. 2016; Carro et al. 2023) and introduces four extensions: (1) dynamic linkages between the sale and rental markets through vacancy, rents, and yields; (2) heterogeneous demand-side trend-following; (3) supply-side trend-following through construction-cost trend anchoring and a momentum-dependent dynamic premium; and (4) housing-equity borrowing that converts unrealized equity into additional borrowing capacity.
Twenty parameters are calibrated using 2001–2015 data and held fixed for post-calibration evaluation over 2016–2020 and 2021–2025, while annual exogenous inputs follow observed historical paths. The model reproduces the shift from moderate price growth to the 2021–2025 surge, as well as rent acceleration, surge-period yield compression, and persistently low market turnover, although it understates the intermediate acceleration of 2016–2020.
…
Mobility Sharing for Social Integration: A Reverse Schelling Model
Hongmou Zhang | Published Thursday, October 15, 2026This model extends Schelling’s segregation model with mobility sharing. Agents of two groups occupy cells of a 32 × 32 grid and repeatedly choose activity destinations subject to a preference threshold, the minimum share of ingroup neighbours they accept. Trips are matched into shared rides between members of different groups, using one of four matching algorithms on a shareability network (maximal cross-group matching, maximum weight matching on contact time, maximum cardinality matching, or random greedy matching) with a maximum detour constraint. After each trip, an agent’s preference threshold changes with the time spent in contact with outgroup members.
Starting from complete segregation, the model examines under which conditions contact during shared trips leads to integration. Besides the main scenario, in which contact always lowers the threshold, it includes two extensions. In the first, a share of adversarial agents becomes less tolerant with contact, and this share grows or shrinks with the current level of segregation, governed by a branching dissimilarity index and a conversion rate. In the second, each contact raises or lowers the threshold with a probability that depends on the agent’s current attitude relative to a compatibility threshold.
Segregation is measured with the index of dissimilarity and the Gini coefficient. The model file includes BehaviorSpace experiments for each analysis in the associated article. The matching step uses the NetworkX library through the Python extension of NetLogo (requires Python 3 with numpy and networkx 3.x).
ABODE - Agent Based Model of Origin Destination Estimation
D Levinson | Published Monday, August 29, 2011 | Last modified Saturday, April 27, 2013The agent based model matches origins and destinations using employment search methods at the individual level.
Peer reviewed Collectivities
Nigel Gilbert | Published Tuesday, April 09, 2019 | Last modified Thursday, August 22, 2019The model that simulates the dynamic creation and maintenance of knowledge-based formations such as communities of scientists, fashion movements, and subcultures. The model’s environment is a spatial one, representing not geographical space, but a “knowledge space” in which each point is a different collection of knowledge elements. Agents moving through this space represent people’s differing and changing knowledge and beliefs. The agents have only very simple behaviors: If they are “lonely,” that is, far from a local concentration of agents, they move toward the crowd; if they are crowded, they move away.
Running the model shows that the initial uniform random distribution of agents separates into “clumps,” in which some agents are central and others are distributed around them. The central agents are crowded, and so move. In doing so, they shift the centroid of the clump slightly and may make other agents either crowded or lonely, and they too will move. Thus, the clump of agents, although remaining together for long durations (as measured in time steps), drifts across the view. Lonely agents move toward the clump, sometimes joining it and sometimes continuing to trail behind it. The clumps never merge.
The model is written in NetLogo (v6). It is used as a demonstration of agent-based modelling in Gilbert, N. (2008) Agent-Based Models (Quantitative Applications in the Social Sciences). Sage Publications, Inc. and described in detail in Gilbert, N. (2007) “A generic model of collectivities,” Cybernetics and Systems. European Meeting on Cybernetic Science and Systems Research, 38(7), pp. 695–706.
Displaying 10 of 203 results for "Nuno Pinto" clear search